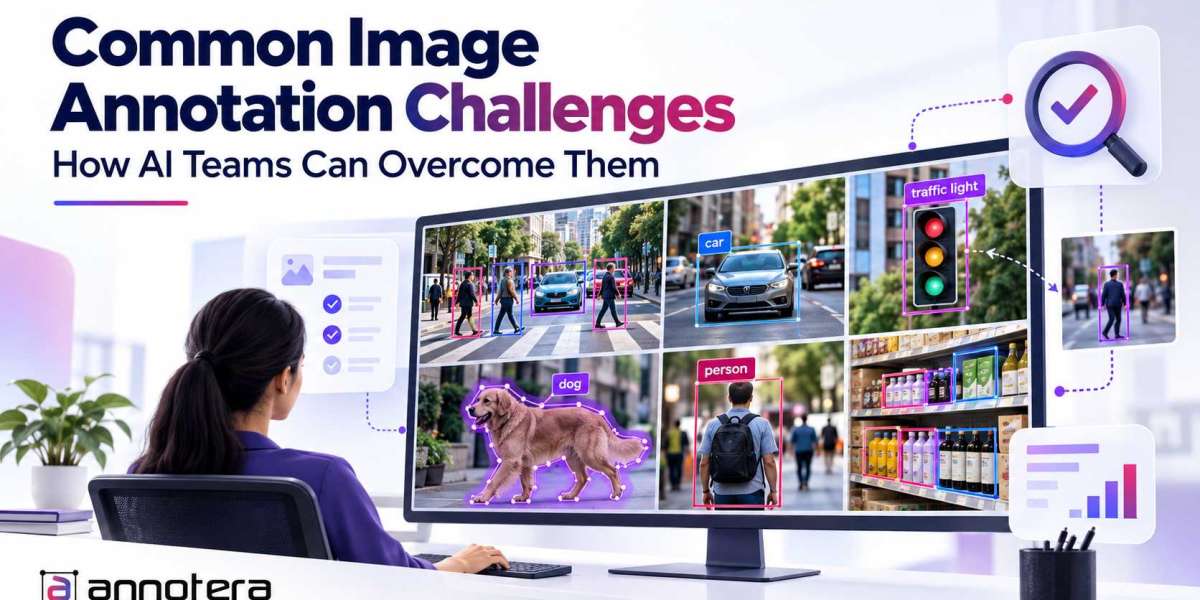

Image annotation is a critical component of developing reliable computer vision systems. From identifying pedestrians in autonomous driving environments to detecting products on retail shelves, AI models depend on accurately labeled visual data to recognize objects, interpret scenes, and make informed predictions. However, creating high-quality image datasets involves more than drawing bounding boxes or assigning labels. AI teams must address inconsistent annotations, complex visual environments, data quality issues, scalability limitations, and evolving project requirements.
As computer vision applications become increasingly sophisticated, overcoming these challenges is essential for building models that perform reliably in real-world conditions. Understanding common annotation problems and adopting effective quality management practices can help organizations improve dataset consistency, accelerate model development, and reduce costly rework.
1. Inconsistent Annotation Quality
One of the most common challenges in image annotation is maintaining consistency across large datasets. Different annotators may interpret labeling instructions differently, particularly when identifying overlapping objects, defining object boundaries, or categorizing visually similar items.
For example, in a retail dataset, one annotator might label a partially visible product as a separate object, while another might exclude it because the product is difficult to identify. Such inconsistencies can introduce noise into training data and negatively affect model performance.
How AI teams can overcome it:
Develop standardized annotation guidelines with clear definitions, visual examples, and edge-case instructions.
Establish consistent rules for object classification, occlusion, boundary placement, and ambiguous images.
Conduct regular calibration sessions to align annotators on labeling expectations.
Implement quality assurance checks and expert reviews for complex annotations.
Partnering with an experienced image annotation company can also help AI teams establish standardized workflows and maintain consistent labeling quality across large-scale projects.
2. Handling Complex and Ambiguous Images
Real-world images frequently contain challenging visual conditions, including poor lighting, motion blur, partial visibility, crowded scenes, and overlapping objects. These factors make it difficult to identify objects accurately and determine their boundaries.
In autonomous driving, for instance, pedestrians may be partially hidden behind vehicles, while road signs may be difficult to recognize in rain or fog. Similarly, security surveillance datasets may contain low-resolution footage and objects captured from unusual angles.
How AI teams can overcome it:
AI teams should develop annotation protocols specifically designed for difficult visual scenarios. These protocols should explain how to handle partially visible objects, uncertain classifications, overlapping instances, and low-confidence labels.
Using suitable annotation techniques is equally important. Bounding boxes work well for many object detection tasks, while polygon annotation and semantic segmentation offer greater precision when models must understand detailed object boundaries.
Teams should also preserve challenging examples in their datasets rather than automatically discarding them. These examples can help models learn to handle the variability encountered during deployment.
3. Managing Large-Scale Annotation Projects
As AI applications expand, organizations often need to annotate hundreds of thousands or even millions of images. Managing these projects internally can place significant pressure on budgets, timelines, staffing, and quality control processes.
A small annotation team may struggle to maintain consistent output while handling increasing data volumes. Rushed labeling can create errors, and insufficient supervision can make those errors difficult to detect before model training begins.
How AI teams can overcome it:
A scalable annotation workflow should combine efficient project management, automation, and structured quality assurance. Teams can divide datasets into manageable batches, establish productivity benchmarks, and monitor annotation accuracy throughout the project.
AI-assisted annotation tools can accelerate repetitive tasks by generating preliminary labels that human annotators subsequently review and correct. This approach reduces manual effort without eliminating human oversight.
For organizations with fluctuating workloads or specialized requirements, image annotation outsourcing services can provide access to trained annotation teams, established workflows, and scalable operational capacity. This allows internal AI teams to focus more on model development, evaluation, and deployment.
4. Maintaining Accurate Labels Across Diverse Datasets
Computer vision models must often process images collected across different locations, devices, environments, and demographic contexts. A dataset containing only ideal lighting conditions, familiar objects, or limited camera perspectives may not adequately represent real-world deployment scenarios.
This lack of diversity can contribute to poor generalization, where a model performs well on familiar training images but struggles with unseen conditions.
How AI teams can overcome it:
Start by defining the visual scenarios the model is expected to encounter. Dataset planning should account for variations in lighting, weather, backgrounds, camera angles, object sizes, and environmental conditions.
Annotation teams should apply consistent taxonomies across all dataset segments while preserving relevant contextual information. For example, autonomous vehicle datasets may require separate labels for pedestrians, cyclists, traffic signals, road markings, and partially occluded vehicles.
AI teams should also review dataset coverage regularly to identify underrepresented categories and difficult scenarios. Targeted data collection and annotation can then address these gaps before they significantly affect model performance.
5. Preventing Annotation Errors and Dataset Bias
Even a large dataset can be unreliable when it contains incorrect labels, missing objects, duplicated images, or systematic labeling bias. These problems can mislead model training and create performance disparities across different conditions or object categories.
For example, if certain objects are consistently omitted from crowded scenes, an object detection model may learn to overlook similar instances during inference.
How AI teams can overcome it:
A comprehensive quality assurance process should include multiple layers of validation. Automated checks can identify missing fields, invalid class labels, duplicate records, and inconsistent annotation formats. Human reviewers can then inspect samples for semantic errors and incorrect object boundaries.
Teams should also measure annotation agreement, track error patterns, and perform targeted audits on high-risk categories. Reviewing model predictions alongside annotated ground truth can help identify suspicious labels and recurring dataset weaknesses.
Importantly, quality assurance should be continuous rather than restricted to the end of a project. Detecting errors early reduces the cost of corrections and prevents flawed annotations from spreading across downstream datasets.
6. Integrating Annotation Tools With Existing AI Workflows
Annotation projects can become inefficient when labeling platforms, data storage systems, and machine learning pipelines operate independently. Manual file transfers, incompatible formats, and inconsistent dataset versions can create delays and introduce additional errors.
How AI teams can overcome it:
Choose annotation tools that support the required formats, annotation types, and integration capabilities. Establish clear processes for importing raw images, exporting labeled datasets, validating outputs, and transferring approved data into training pipelines.
Version control is equally important. Teams should document changes to annotation guidelines, class definitions, and dataset revisions so that model performance can be traced to the corresponding training data.
A well-integrated workflow minimizes operational friction and makes it easier to reproduce experiments, compare model versions, and maintain dataset traceability.
7. Balancing Annotation Costs, Speed, and Accuracy
AI teams frequently face pressure to reduce annotation costs while delivering datasets quickly. However, prioritizing speed or the lowest cost per image can result in inconsistent labels, increased rework, and weaker model performance.
The objective should be to optimize the total cost of producing usable, high-quality data rather than simply maximizing the number of images annotated per hour.
How AI teams can overcome it:
Use risk-based quality control to allocate more review effort to complex images, rare categories, and annotations that directly affect critical model decisions. Combine automation with human validation wherever appropriate, and monitor both productivity and error rates.
When evaluating image annotation outsourcing services, organizations should consider domain expertise, quality assurance procedures, data security, scalability, and the ability to meet project-specific requirements—not just pricing.
A reliable annotation partner should work within clearly defined acceptance criteria and provide measurable evidence of dataset quality.
Conclusion: Building Better AI Starts With Better Annotation
Image annotation challenges can affect every stage of the computer vision development lifecycle, from initial training to real-world deployment. Inconsistent labeling, complex imagery, scaling difficulties, dataset bias, and inefficient workflows can all undermine model reliability if left unaddressed.
The solution lies in combining standardized annotation guidelines, representative datasets, appropriate tools, continuous quality assurance, and scalable operational processes. AI teams that treat annotation as a strategic component of model development can build stronger datasets and improve the reliability of their computer vision systems.
Annotera helps AI teams address these challenges with structured data annotation workflows designed around project requirements, annotation quality, and scalability. Whether you are developing object detection systems, segmentation models, or advanced computer vision applications, the right annotation strategy can make a meaningful difference.
Ready to improve your computer vision training data? Connect with Annotera to explore image annotation solutions tailored to your AI development goals.